Gemma 4 26B A4B: useful local MoE, not the final answer
Gemma 4 26B A4B is listed as an on-device MoE model with 26B total and roughly 4B active parameters. In Local Model Bench it remains a useful local baseline, but newer Qwen3.6 27B results moved the local bar higher.
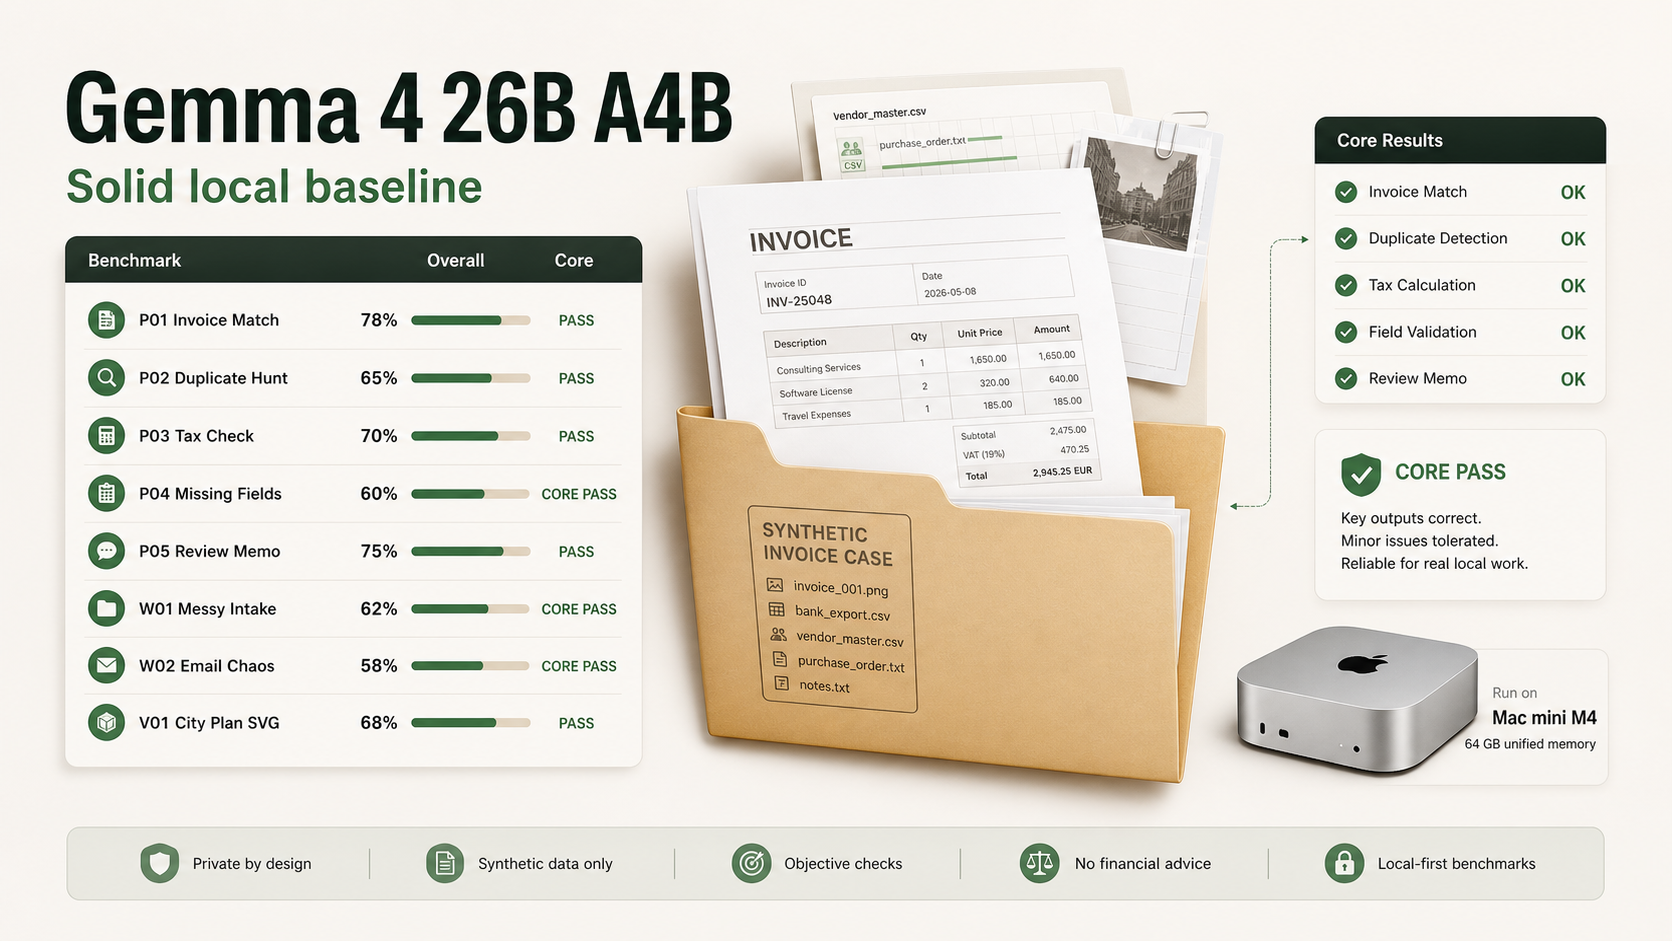
The 26B A4B variant is interesting because it is not simply a small dense model. LM Studio lists it as a 26B total, active-4B mixture-of-experts model with vision input, tool-use training, and reasoning support.
That positioning matches the local-use promise: a model that should be fast enough to run on serious desktop hardware while still carrying enough capacity for document and workflow tasks. Our run tested whether that promise survives messy paperwork.
Why the MoE shape matters
Gemma 4 26B A4B is interesting because it represents a practical local-model compromise. The model is listed as 26B total parameters with roughly 4B active per token. That makes it sound like a larger model while trying to keep inference closer to a smaller active footprint.
For local users, that tradeoff matters. A model that is technically strong but too slow to use is less useful than a model that can sit in a desktop workflow and respond without turning the machine into a space heater.
What it did well
In the current paperwork suite, Gemma 4 26B A4B reached a 61.1% Practical Score with four strict resolved cases and seven core passes out of nine. That is a real result. It means the model was often close to the right audit facts even when exact closure failed.
The result was especially useful during calibration because it showed the benchmark was not impossibly hard for local models. Smaller or weaker rows failed much more broadly, while Gemma produced enough near misses to make the resolved/core split meaningful.
Where it lost ground
The misses are familiar: proof details, exact artifacts, and workflow closure. The model could often understand the paperwork but still fail the final contract. That makes it useful for assisted review and risky for unattended document automation.
The separate City Plan SVG sample also failed, which keeps the result from looking like a general-purpose win. Gemma did better at paperwork logic than at constrained visual generation in this suite.
Why Qwen changed the readout
When this note was first drafted, Gemma 4 26B A4B was the strongest local row. After additional runs, Qwen3.6 27B moved ahead with a higher practical score and stronger text-only diagnostic performance. That does not make the Gemma result irrelevant. It changes its role.
Gemma 4 26B A4B is now better read as a useful local MoE baseline: good enough to take seriously, not strong enough to be the current target.
Practical use case
The conservative recommendation is human-in-the-loop paperwork triage. Use it to draft structured outputs, find likely mismatches, and surface review candidates. Do not treat it as a final accounting worker without checks.
That is not a failure of the model alone. It is the shape of the task. Private-document workflows punish small mistakes because the final artifact matters.
Where it worked
- Strong local practical score in the frozen v1 paperwork suite.
- Seven of nine cases reached core-pass level, which matters more than one-off formatting wins.
- Handled the mixed paperwork workflow better than smaller local candidates.
Where it failed
- Still missed strict resolution on several cases because proof and exact artifact details matter.
- The separate City Plan SVG sample did not produce a usable visual artifact.
- Near misses still need manual review before treating outputs as dependable.