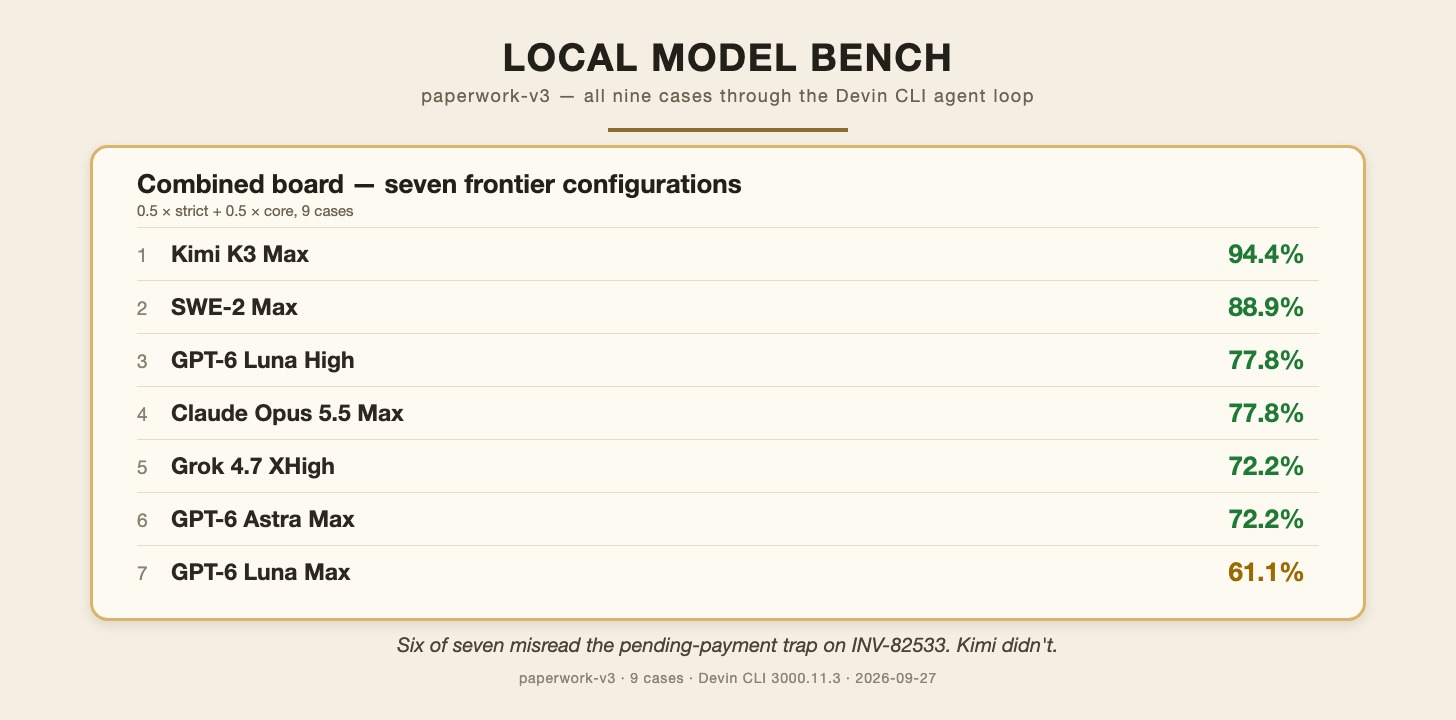
paperwork-v3 Kimi K3 Max tops paperwork-v3 via Devin CLI: SWE-2 beats GPT-6 and Opus Seven frontier model configs ran all nine paperwork-v3 cases through Devin CLI's agent loop. Kimi K3 Max takes first place on the board (94.4%), SWE-2 Max second (88.9%), ahead of GPT-6 Astra Max, Claude Opus 5.5 Max and Grok 4.7 XHigh.
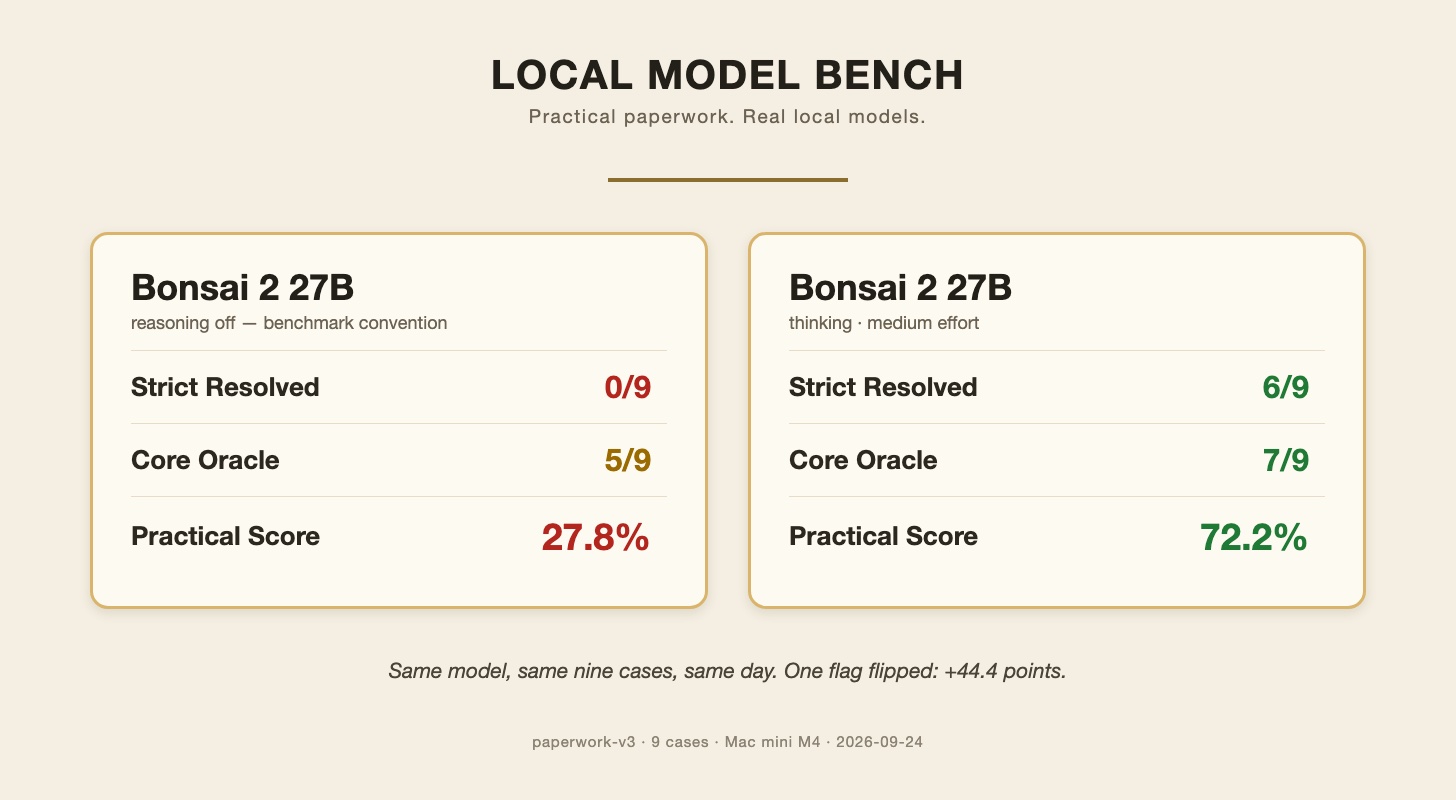
paperwork-v3 Bonsai 2 27B on paperwork-v3: 0/9 resolved without thinking, 6/9 with (72.2% practical) Bonsai 2 27B is PrismML's ternary successor on a Qwen3.8-27B backbone. On paperwork-v3 it scored 0/9 strict without thinking and 6/9 strict, 7/9 core (72.2% practical) at medium thinking effort — a 44.4-point mode split.
paperwork-v3 Qwen3.8 27B on paperwork-v3: 3/9 closed, down from Qwen3.6 27B's 5/9 on the same nine cases Qwen3.8 27B is the successor to Qwen3.6 27B, which currently leads the Local Model Bench local row on the nine-case paperwork-v3 suite. On this generation Qwen3.8 closed 3/9 strictly and 7/9 core-oracle for a practical score of 55.6%. Qwen3.6 27B closed 5/9 strictly and 8/9 core-oracle for 72.2% on