OpenAI GPT-5.5 (Codex CLI): what clean workflow closure looks like
Codex is not a local LM Studio run. It is kept as a reference line for what stronger agentic tooling does on the same public cases, using the same artifacts and hidden-oracle checks.
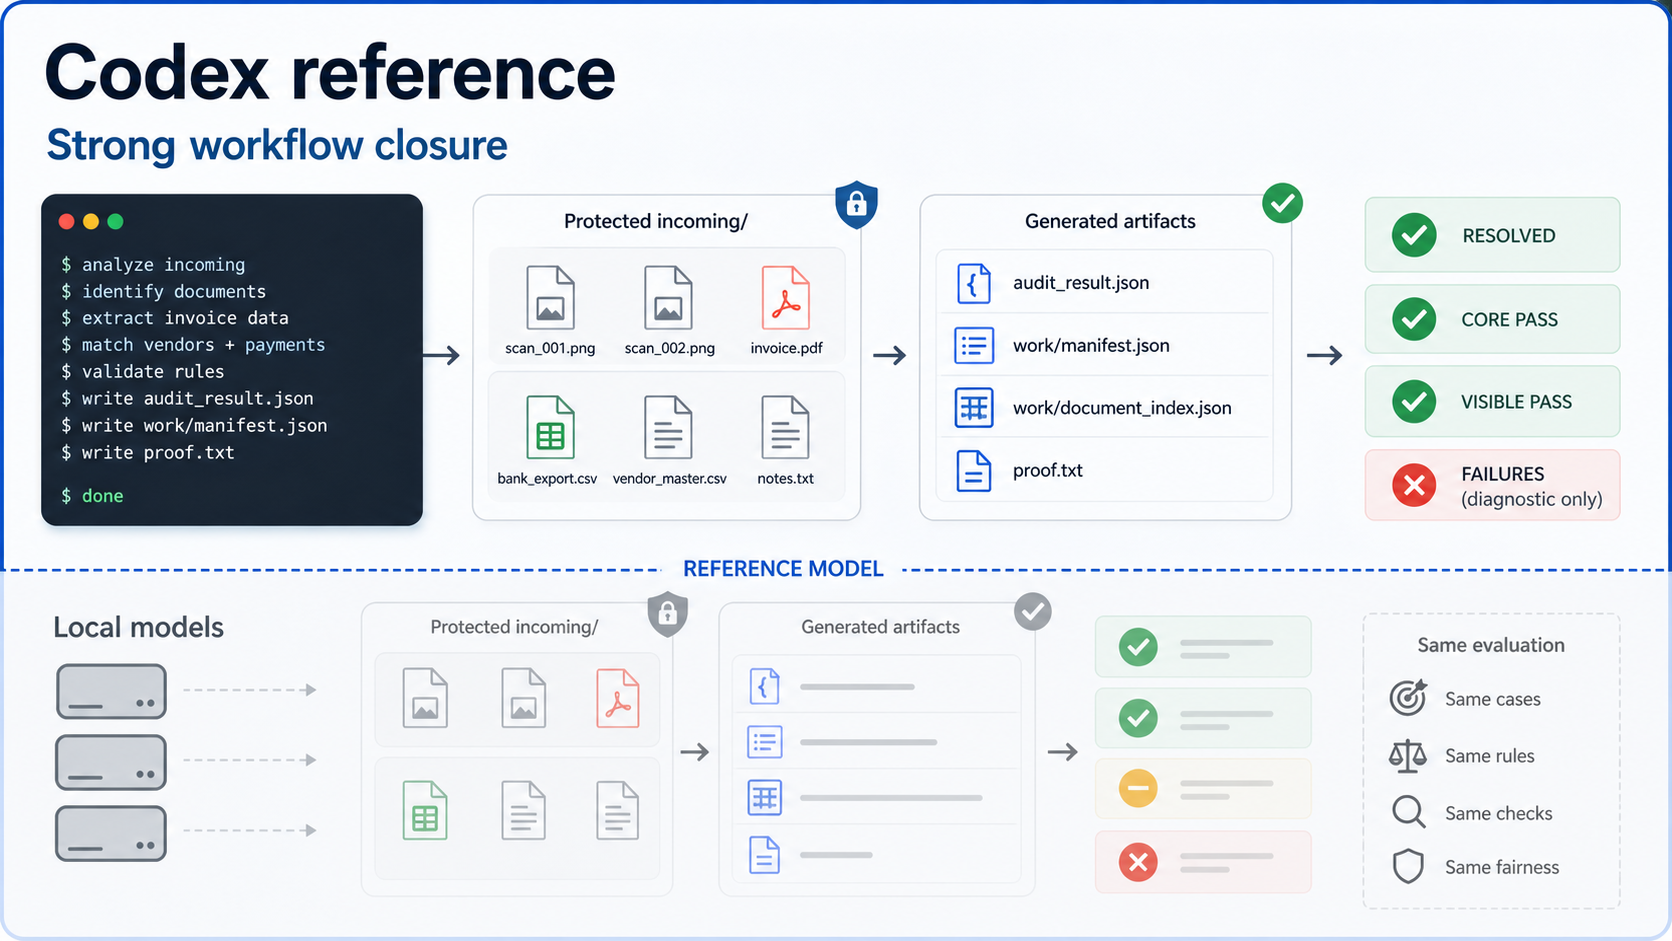
The Codex row is intentionally not presented as a local-model victory lap. It is a ceiling/reference line: a stronger agentic coding environment running the same public paperwork cases.
That reference is useful because it shows which failures are benchmark difficulty rather than local-only weakness. Even the reference run still missed proof/evidence details, which is exactly why Local Model Bench separates core pass from resolved pass.
Where it worked
- Best current practical score across the full public case set.
- Strong at preserving protected input folders while producing required artifacts.
- Most failures were narrow near misses rather than broad document misunderstanding.
Where it failed
- Still failed one case strictly and had proof/evidence misses.
- Not directly comparable to local-only LM Studio runs.
- Useful as a ceiling/reference, not as the point of the site.