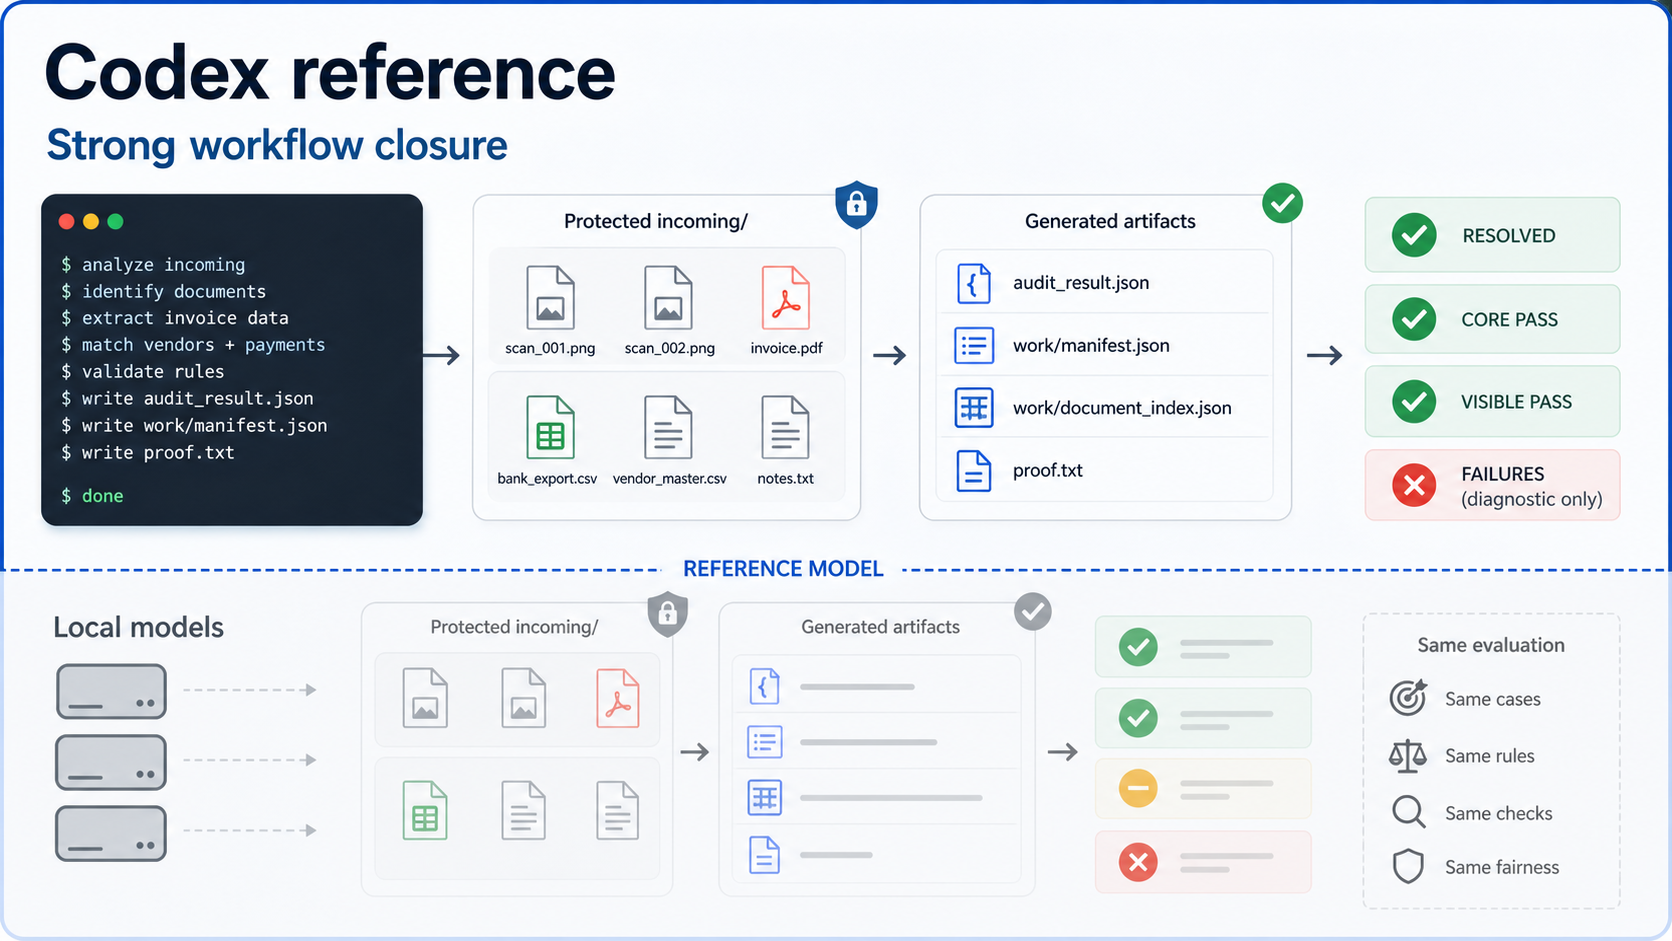
reference Why Codex can lose to a local model In the text-only paperwork benchmark, a local Qwen model beats the Codex reference row. That does not mean the local model is generally smarter. It means this benchmark rewards exact workflow closure, and Codex repeatedly missed the boring final checksum.
reference OpenAI GPT-5.5 (Codex CLI): what clean workflow closure looks like Codex is not a local LM Studio run. It is kept as a reference line for what stronger agentic tooling does on the same public cases, using the same artifacts and hidden-oracle checks.
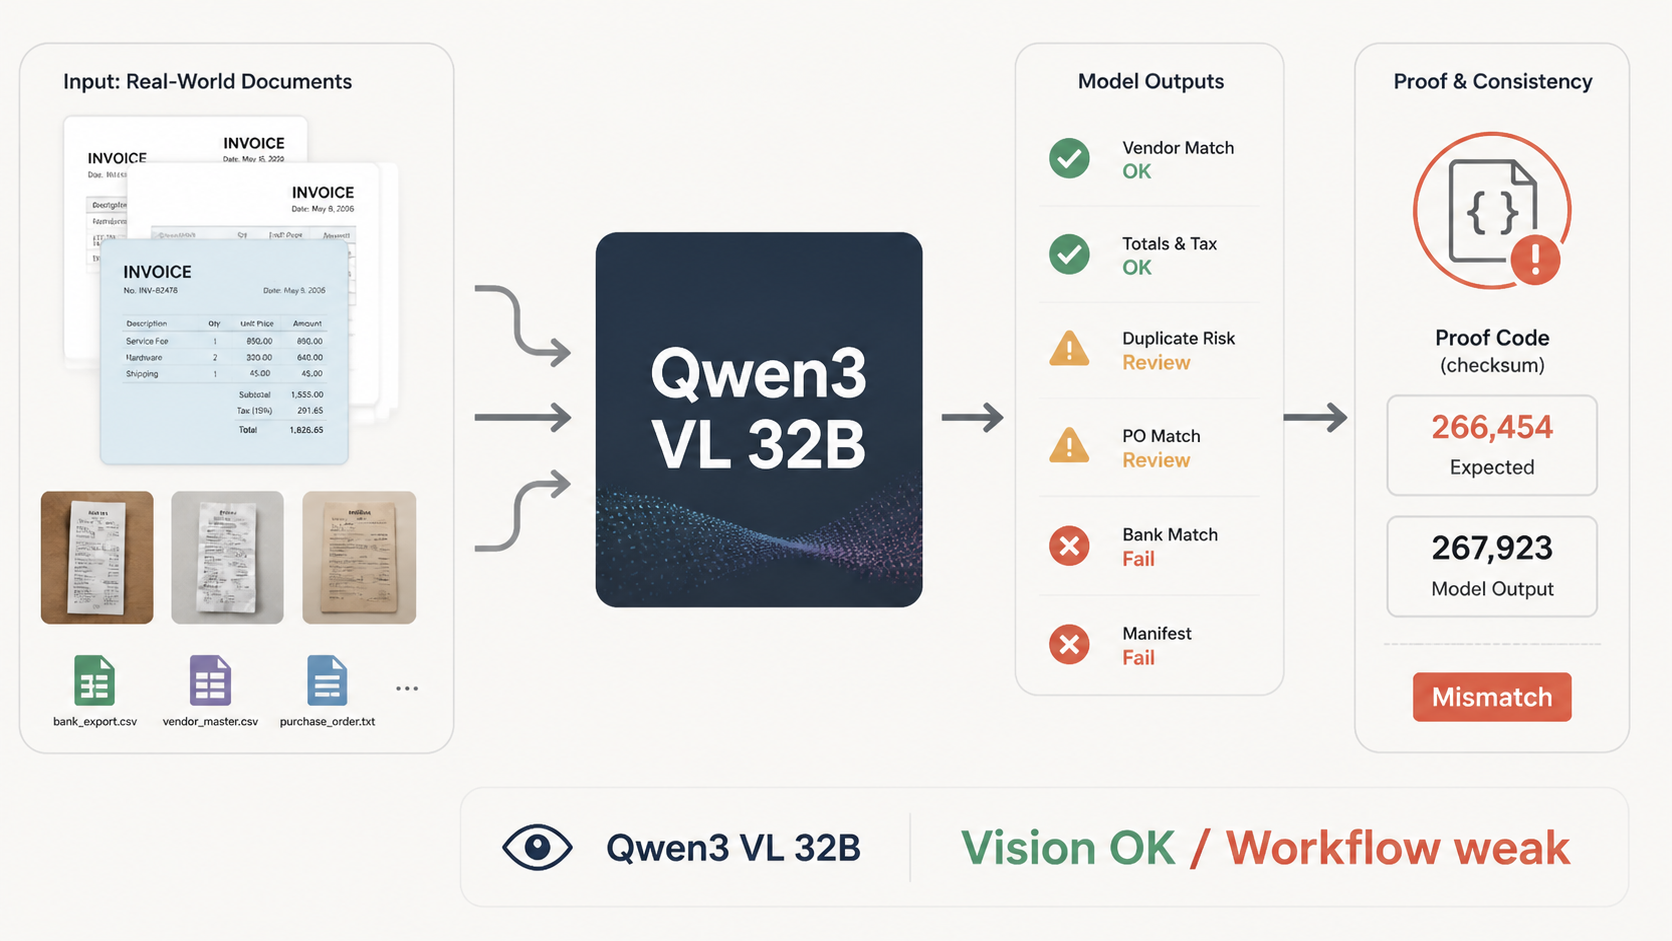
reference Qwen3 VL 32B in a paperwork workflow test Qwen3-VL is positioned as a strong vision-language model for long-context image reasoning. In this benchmark it read many document facts correctly, then repeatedly lost the run at proof codes, duplicate-risk logic, and workflow closure.