Qwen3 VL 32B in a paperwork workflow test
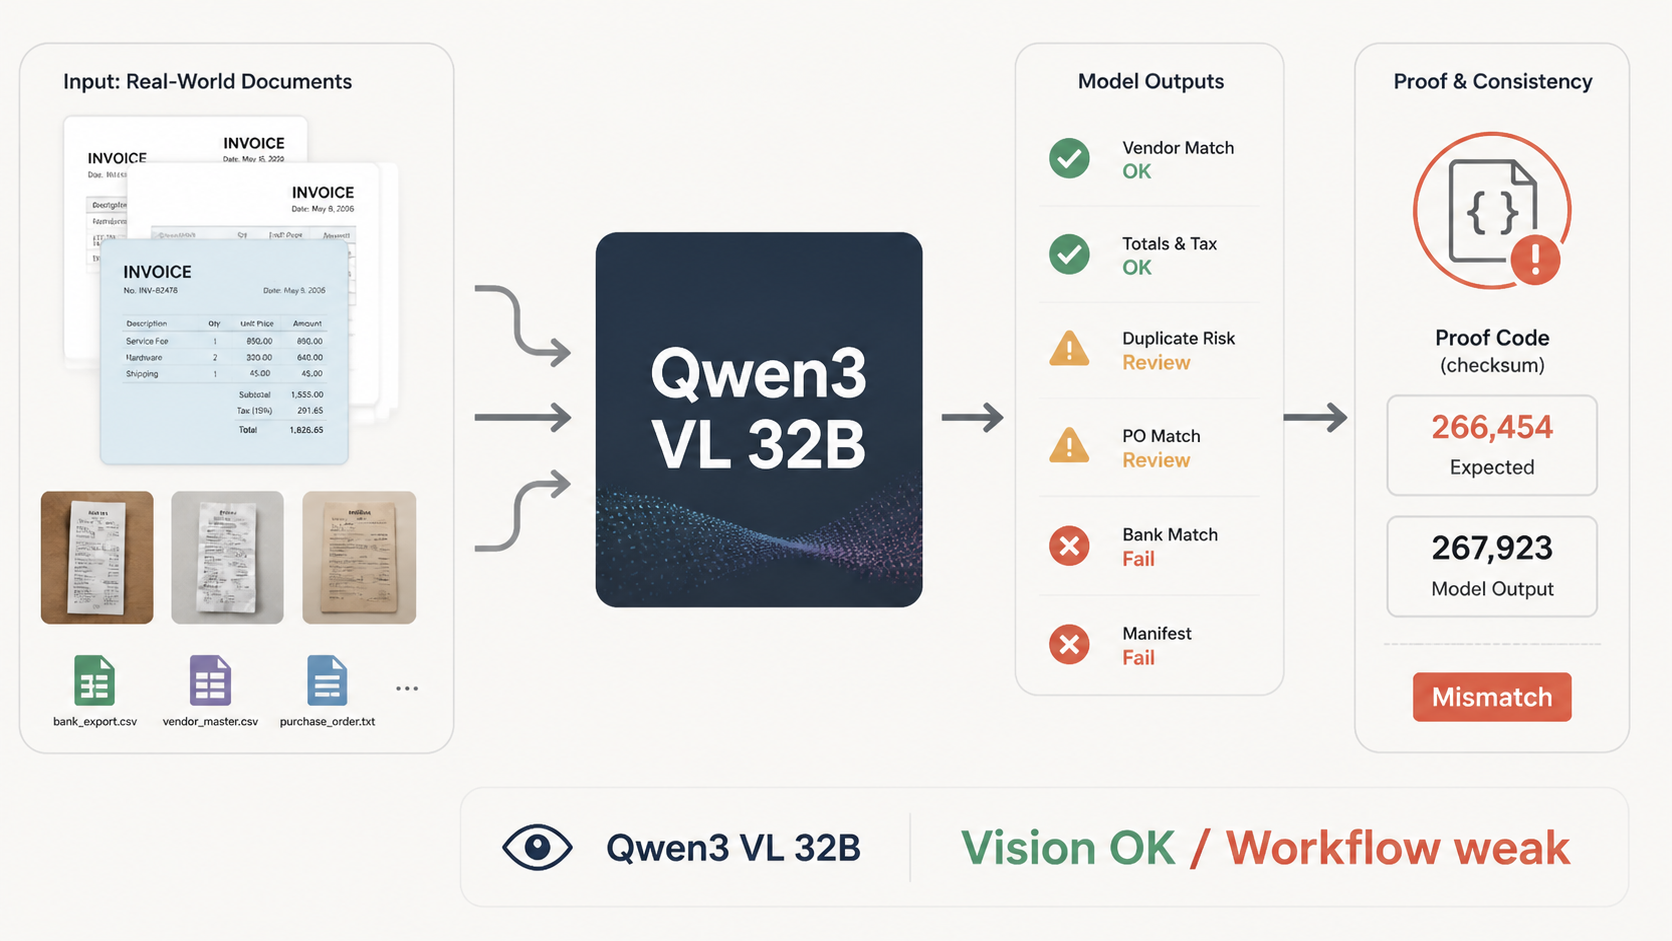
Qwen3-VL is positioned as a strong vision-language model for long-context image reasoning. In this benchmark it read many document facts correctly, then repeatedly lost the run at proof codes, duplicate-risk logic, and workflow closure.
Qwen3-VL-32B-Instruct is a plausible candidate for local or semi-local document work: it is a 33B-parameter vision-language model with image-text input, and its model card positions Qwen3-VL as the strongest vision-language generation in the Qwen line so far.
That makes it tempting to treat the model as a document assistant. Local Model Bench tested something narrower and less glamorous: can it turn synthetic invoice scans and messy intake folders into exact final artifacts under hidden-oracle checks?
Where it worked
- Extracted core fields correctly in the easier invoice-image cases.
- Handled visible invoice IDs, warning labels, and document types better than its strict score suggests.
- Generated a valid City Plan SVG sample.
Where it failed
- Repeated proof-code failures even when the business facts were otherwise correct.
- Missed duplicate-risk and revision-style traps.
- Produced required workflow files, but several intermediate artifacts did not match the hidden oracle.