Ollama vs. LM Studio: speed is not the whole benchmark
We ran the same Mistral Small family through LM Studio and Ollama on a Mac mini M4. Ollama was slightly faster in the tiny runtime check, but both runtimes exposed the same practical problem: the model still failed exact paperwork closure.
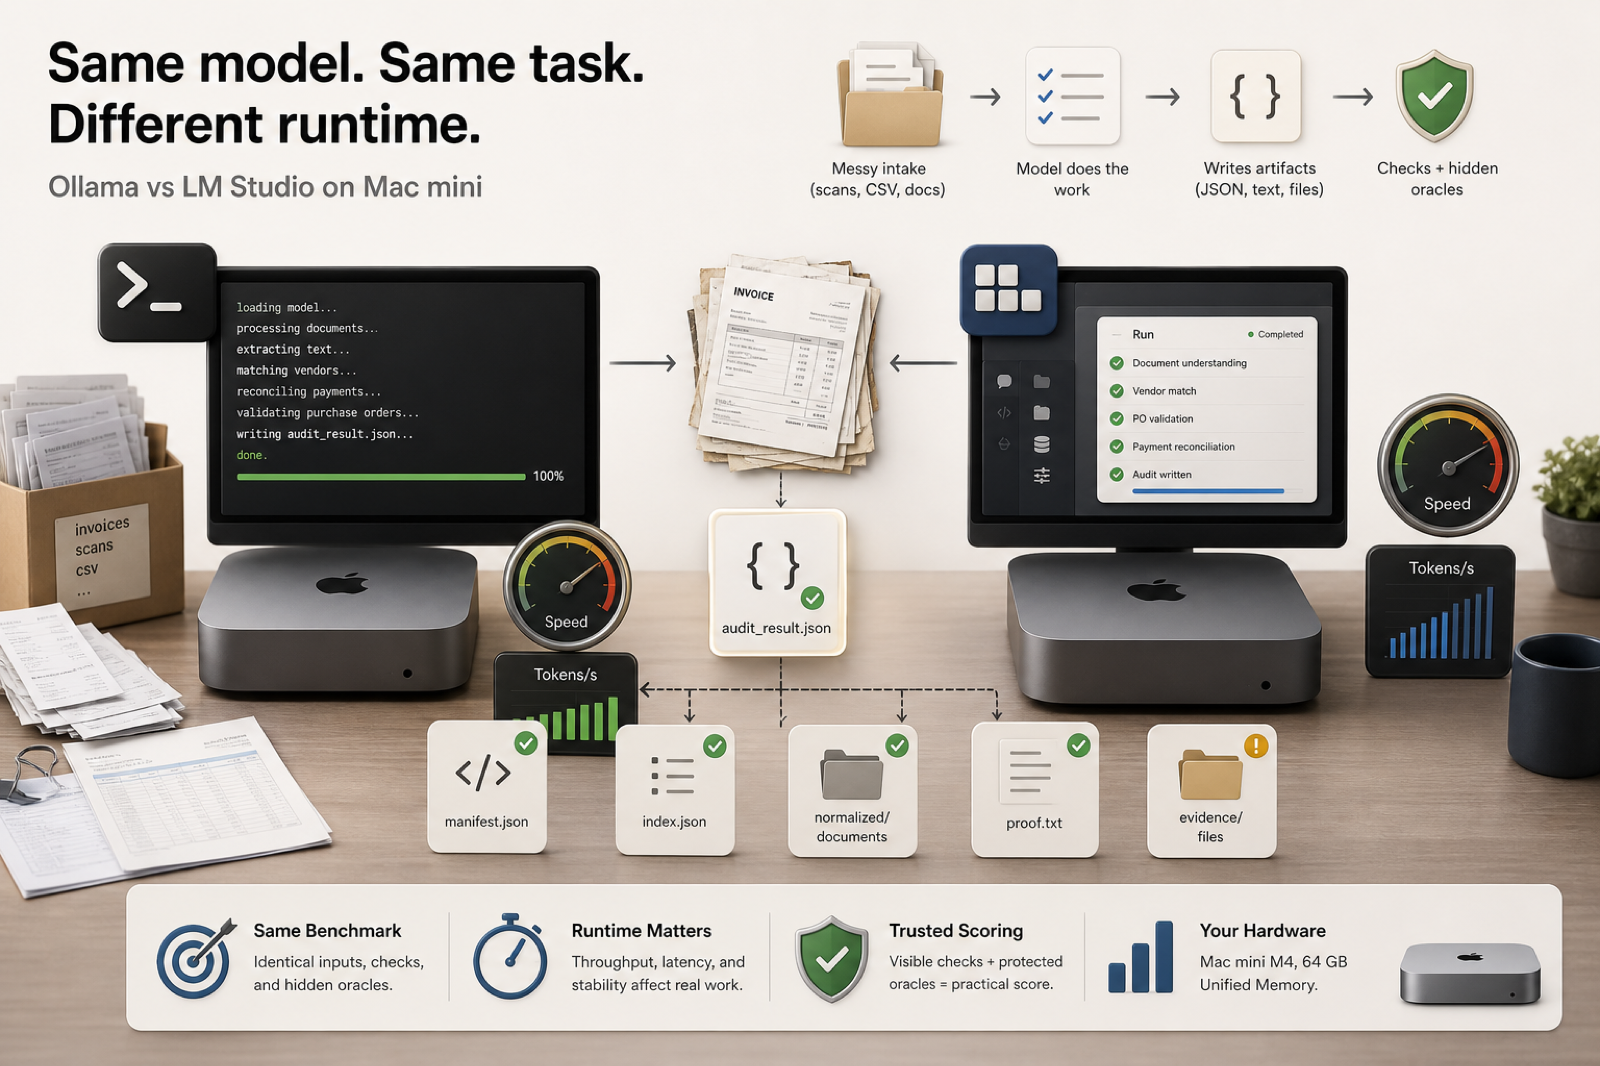
Runtime comparisons are tempting because they produce clean numbers: seconds, tokens per second, load time, and memory behavior. Those numbers matter. But for local desktop work, they are not enough.
This note compares `mistralai/mistral-small-3.2` in LM Studio with `mistral-small:24b` in Ollama on the same Mac mini M4 with 64 GB unified memory. The useful result is not a simple winner. It is a reminder that speed has to be read together with output quality.
What was tested
The first pass used three tiny reproducible prompts: one JSON invoice extraction, one proof-code calculation, and one short CSV artifact. The goal was not to rank the model broadly. The goal was to see whether the same model family behaves differently through two local runtimes.
After that, the Ollama run was pushed through the Paperwork Text-Only diagnostic: five synthetic invoice cases where the model receives normalized document extracts instead of generated invoice images. That removes OCR and vision from the equation and tests bookkeeping, classification, warning logic, evidence paths, and exact final JSON.
Runtime readout
In the tiny runtime check, Ollama was slightly faster by native generation speed: about 14.7 tokens per second compared with about 12.7 tokens per second for LM Studio. Wall-clock time was less clean because the first request includes runtime overhead and model loading behavior.
That makes the result useful but limited. A small prompt set is good for smoke testing and catching obvious runtime differences. It is not enough to declare one runtime better for real work.
Where the simple speed story breaks
The proof-code prompt is where the neat runtime story fell apart. The expected operation required extracting the numeric part of an invoice ID and adding it to two other terms. LM Studio left the invoice ID inside the expression. Ollama returned a short numeric answer, but it was also wrong.
That matters because the Paperwork Trial is full of these small closure steps. A model can read most fields correctly and still lose the case because it cannot finish the arithmetic, evidence, warning, or proof-code step exactly.
Paperwork Text-Only result
On the five-case Paperwork Text-Only diagnostic, Ollama's `mistral-small:24b` reached the same practical result as the earlier LM Studio run: 0/5 strict resolved cases and 1/5 core passes. Ollama did a little better on check count, mostly because it produced valid JSON more consistently.
That distinction is worth keeping. Format robustness is real. But it is not the same as resolving the workflow. The model still missed proof codes, warning codes, invoice classification details, duplicate-risk handling, or exact totals across the harder cases.
What this says about runtimes
This is not a claim that Ollama is better than LM Studio, or that LM Studio is better than Ollama. It is a narrower observation: for this model family and this small local setup, Ollama was a little faster and slightly cleaner on formatting, but the model's core weakness remained.
That is the practical lesson. Runtime matters for user experience, battery, memory, batch throughput, and whether a model is pleasant to run. But Local Model Bench is not trying to reward pleasant failure. The final artifact has to be correct.
Practical readout
For Mistral Small on this benchmark, changing the local runtime did not turn a weak paperwork result into a strong one. It changed the shape of the failure slightly.
That is still useful. If a model produces malformed output in one runtime and valid JSON in another, the runtime deserves credit. But if both runs miss the same proof and bookkeeping logic, the bottleneck is probably the model-task fit, not just the wrapper around it.
Where it worked
- Ollama exposed useful native timing data.
- Ollama was slightly faster in the tiny generation-speed check.
- Ollama produced valid JSON a little more consistently in the text-only diagnostic.
- Both runtimes completed the small prompt set without empty output.
Where it failed
- Both runtime paths failed the tiny proof-code arithmetic prompt.
- Both Paperwork Text-Only runs resolved 0/5 cases strictly.
- The model family still missed exact bookkeeping closure on most cases.
- The experiment does not yet compare memory pressure, long-context behavior, or batch throughput.