Local Model Bench
  • Home
  • Cases
  • Methodology
  • About
Sign in Subscribe

runtime note

A collection of 2 posts
Qwen3.6 MTP worked. The artifact still matters.
runtime note

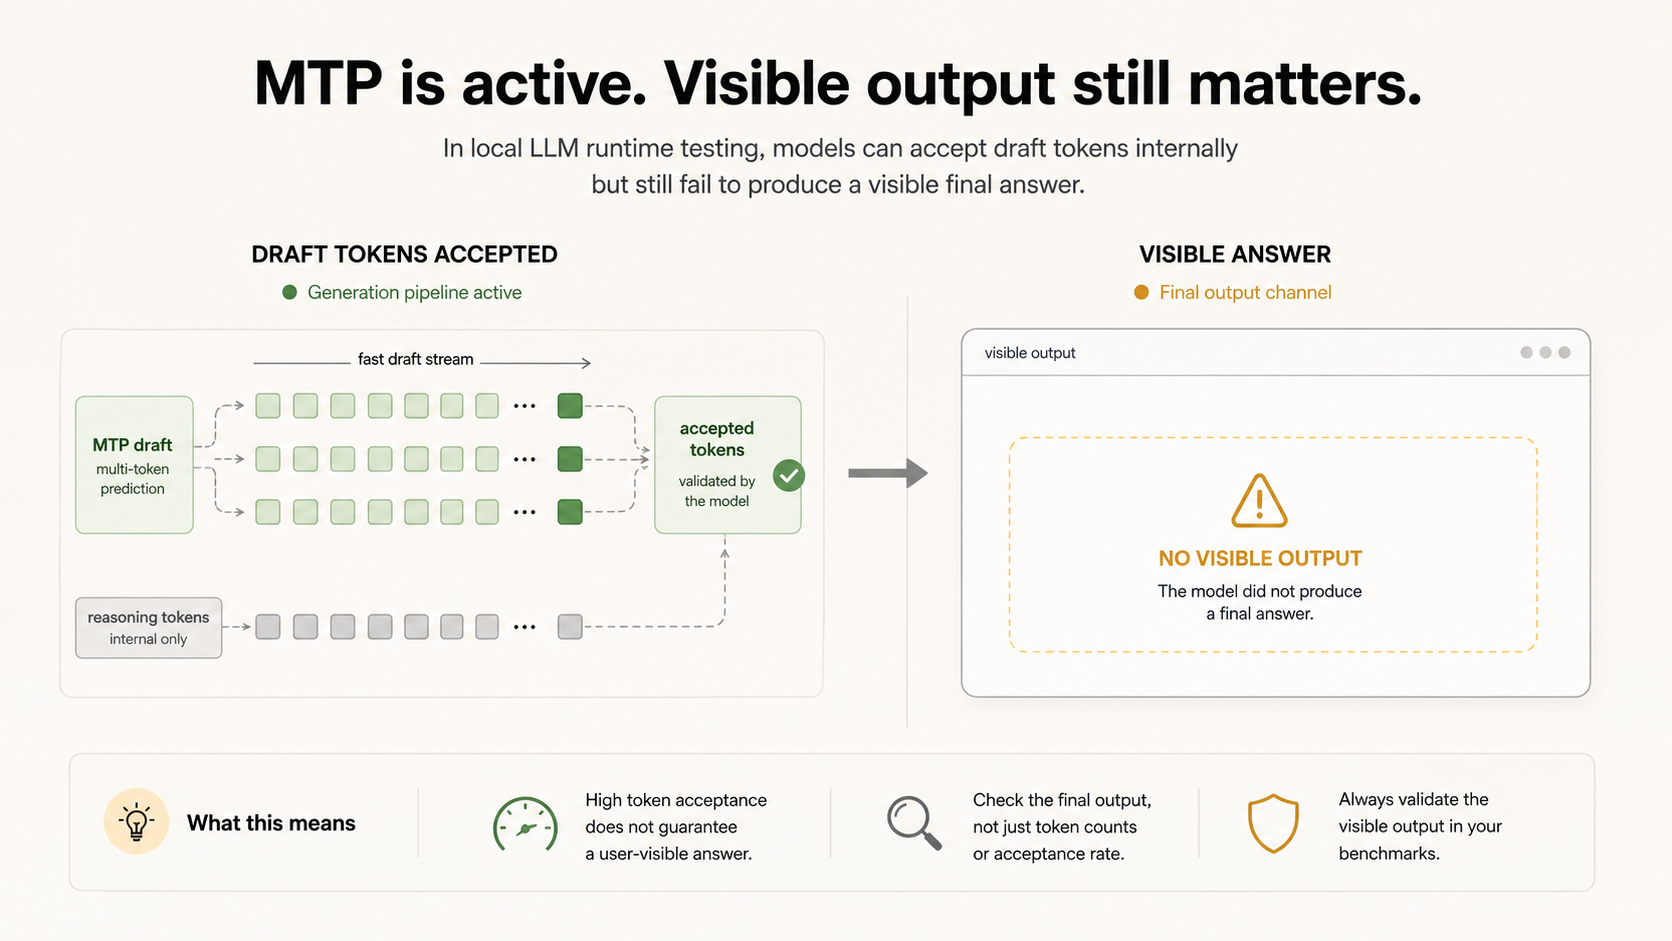
Qwen3.6 MTP worked. The artifact still matters.

Qwen3.6 MTP is the local model people are arguing about right now. In our Mac mini checks, LM Studio showed a small speed gain and llama.cpp showed a tiny gain with the right flags. In a five-case text-only paperwork run, MTP solved 5/5 strict while non-MTP solved 4/5 strict. The speed difference wa
31 May 2026 8 min read
Ollama vs. LM Studio: speed is not the whole benchmark
runtime note

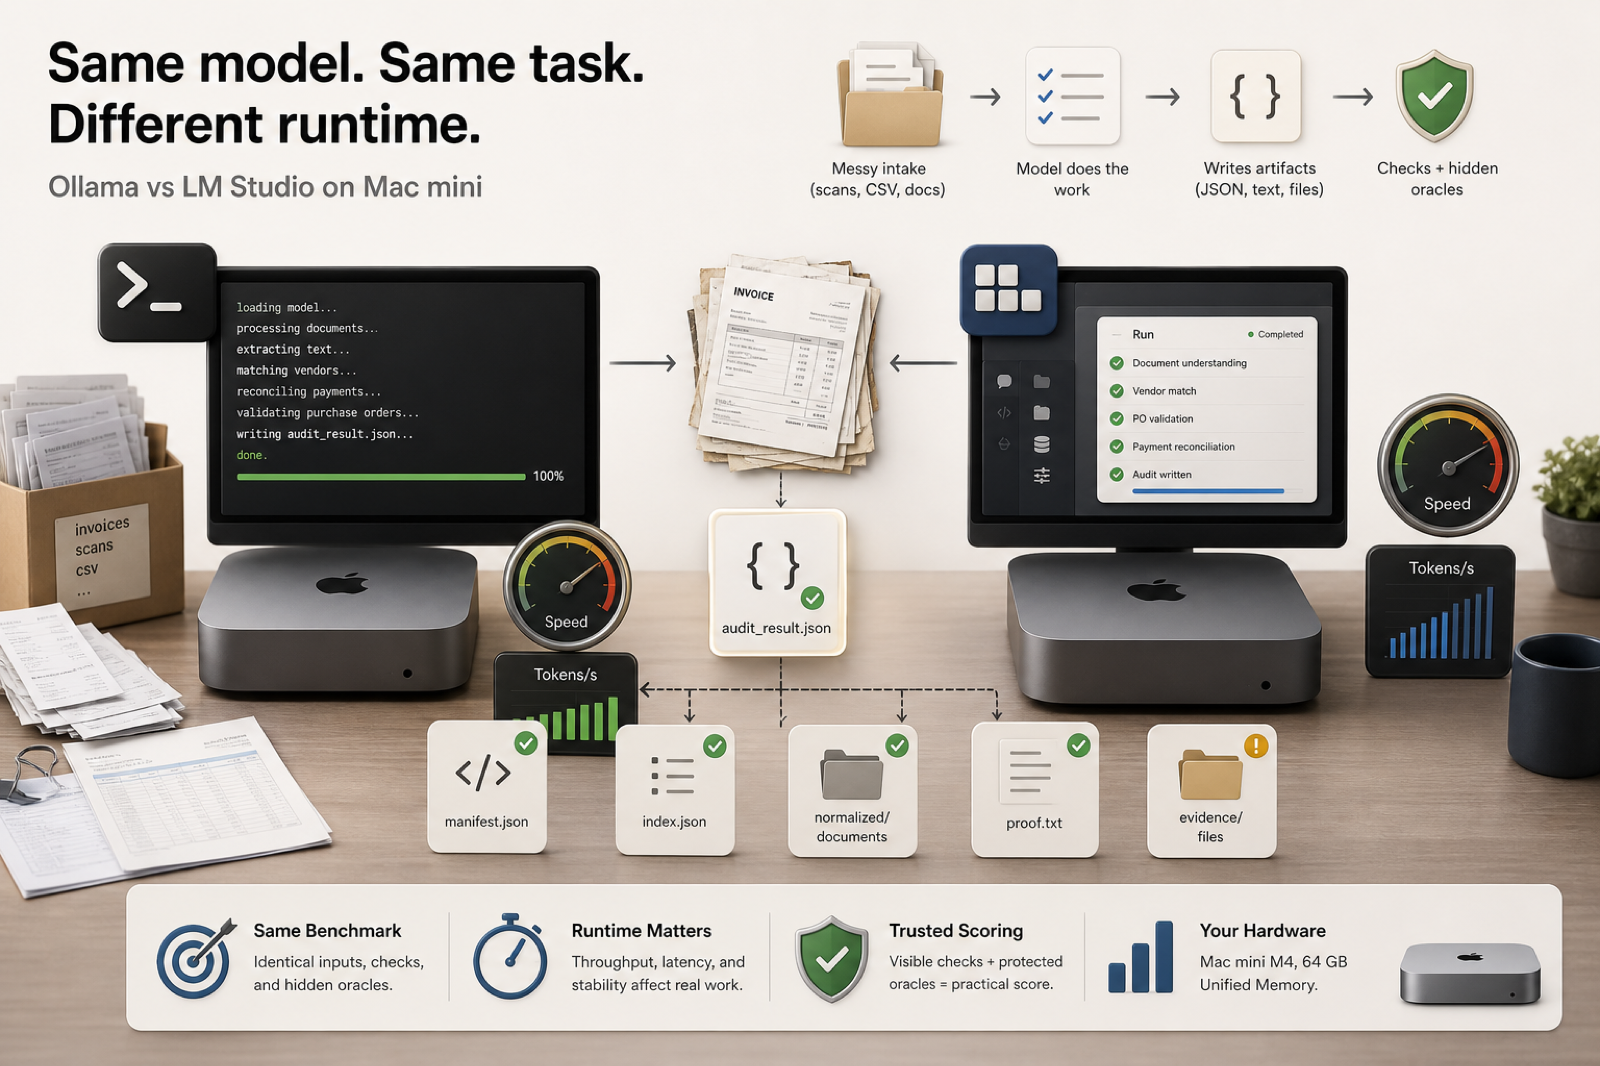
Ollama vs. LM Studio: speed is not the whole benchmark

We ran the same Mistral Small family through LM Studio and Ollama on a Mac mini M4. Ollama was slightly faster in the tiny runtime check, but both runtimes exposed the same practical problem: the model still failed exact paperwork closure.
26 May 2026 3 min read
Page 1 of 1
Local Model Bench © 2026
  • Sign up
Powered by Ghost