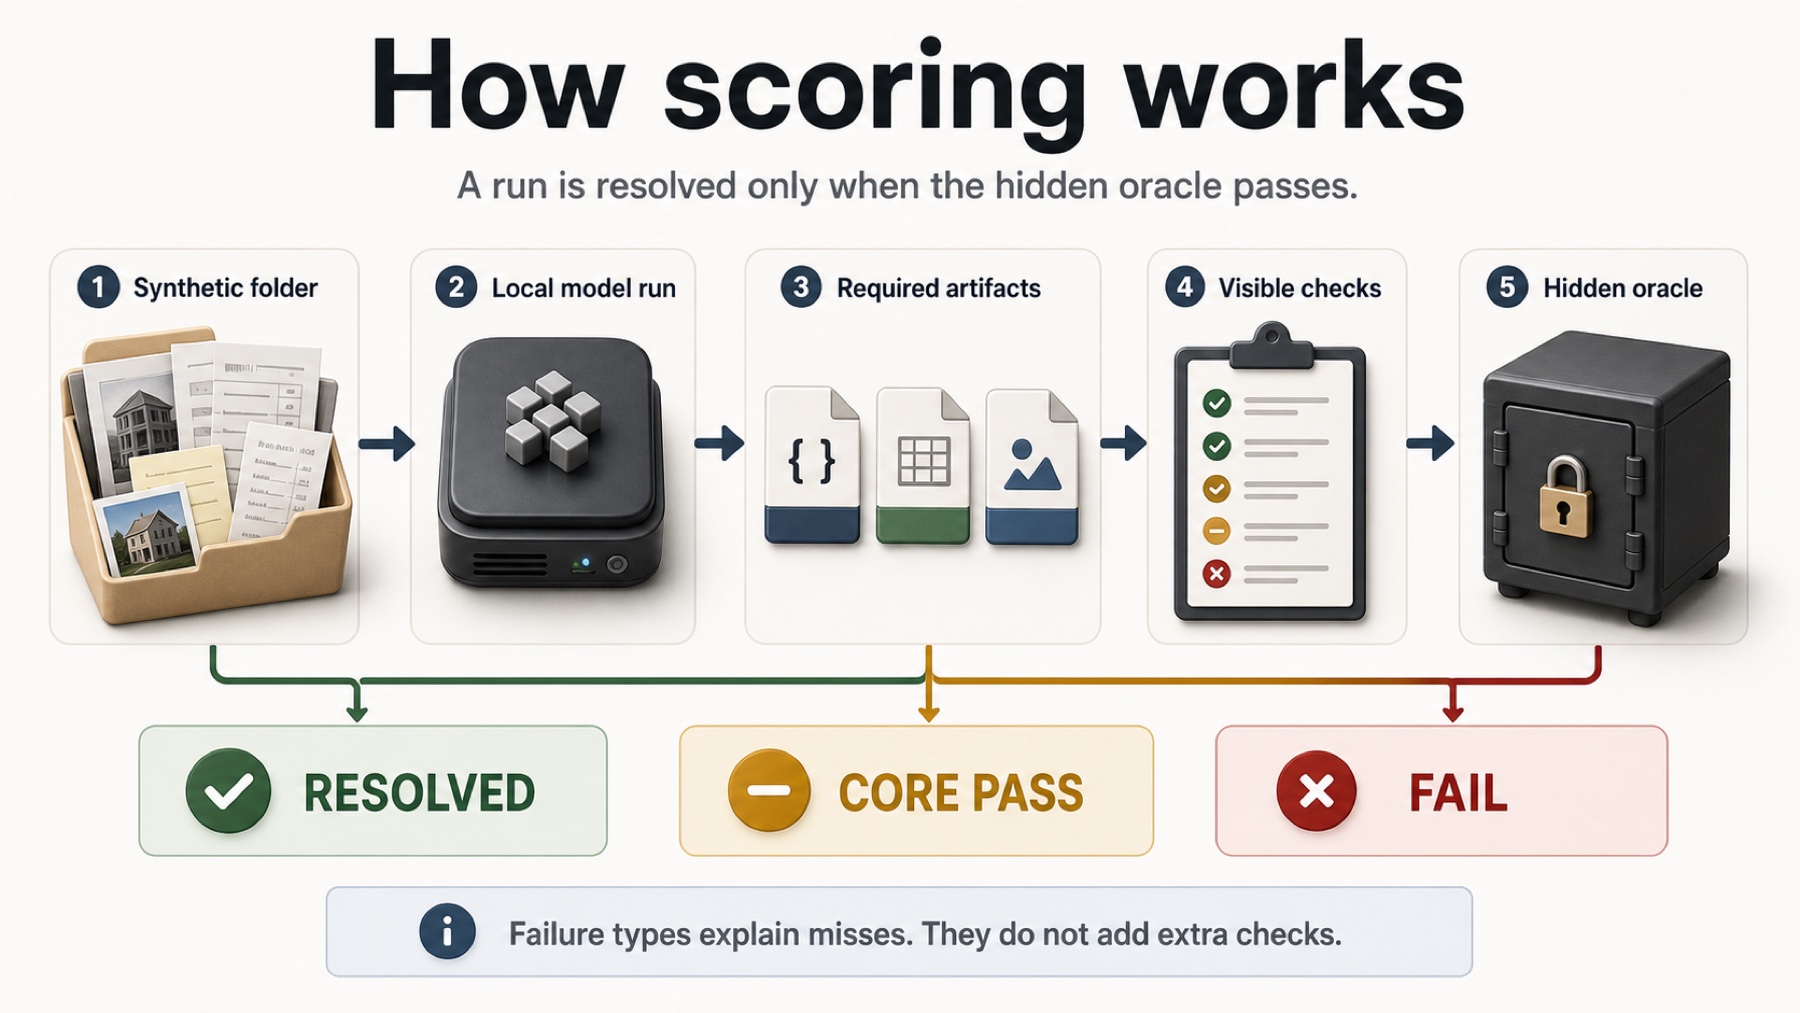
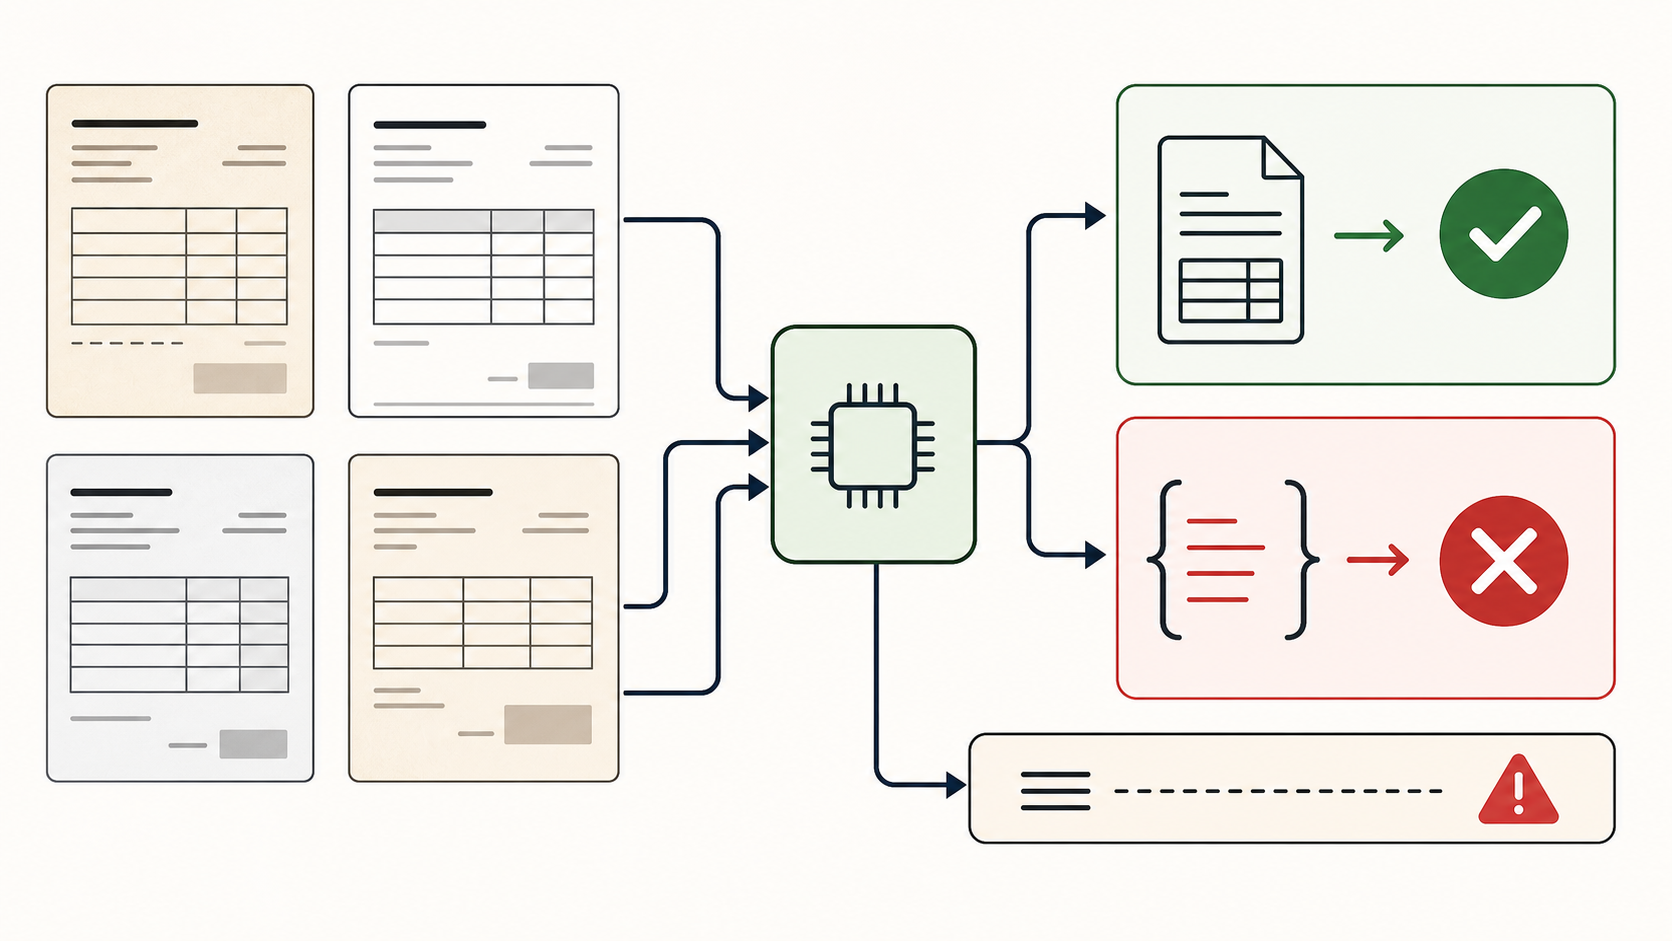
methodology How to benchmark local LLMs for private documents A useful local LLM benchmark should test more than chat quality. For private document work, the hard part is messy inputs, source selection, structured artifacts, hidden oracles, and exact workflow closure.
local Qwen3.6 27B on a Mac mini: the current local model to beat Qwen3.6 27B is the strongest local LM Studio result in the current Local Model Bench suite. It did not solve everything, but it handled synthetic paperwork better than the larger-looking local alternatives we tested so far.
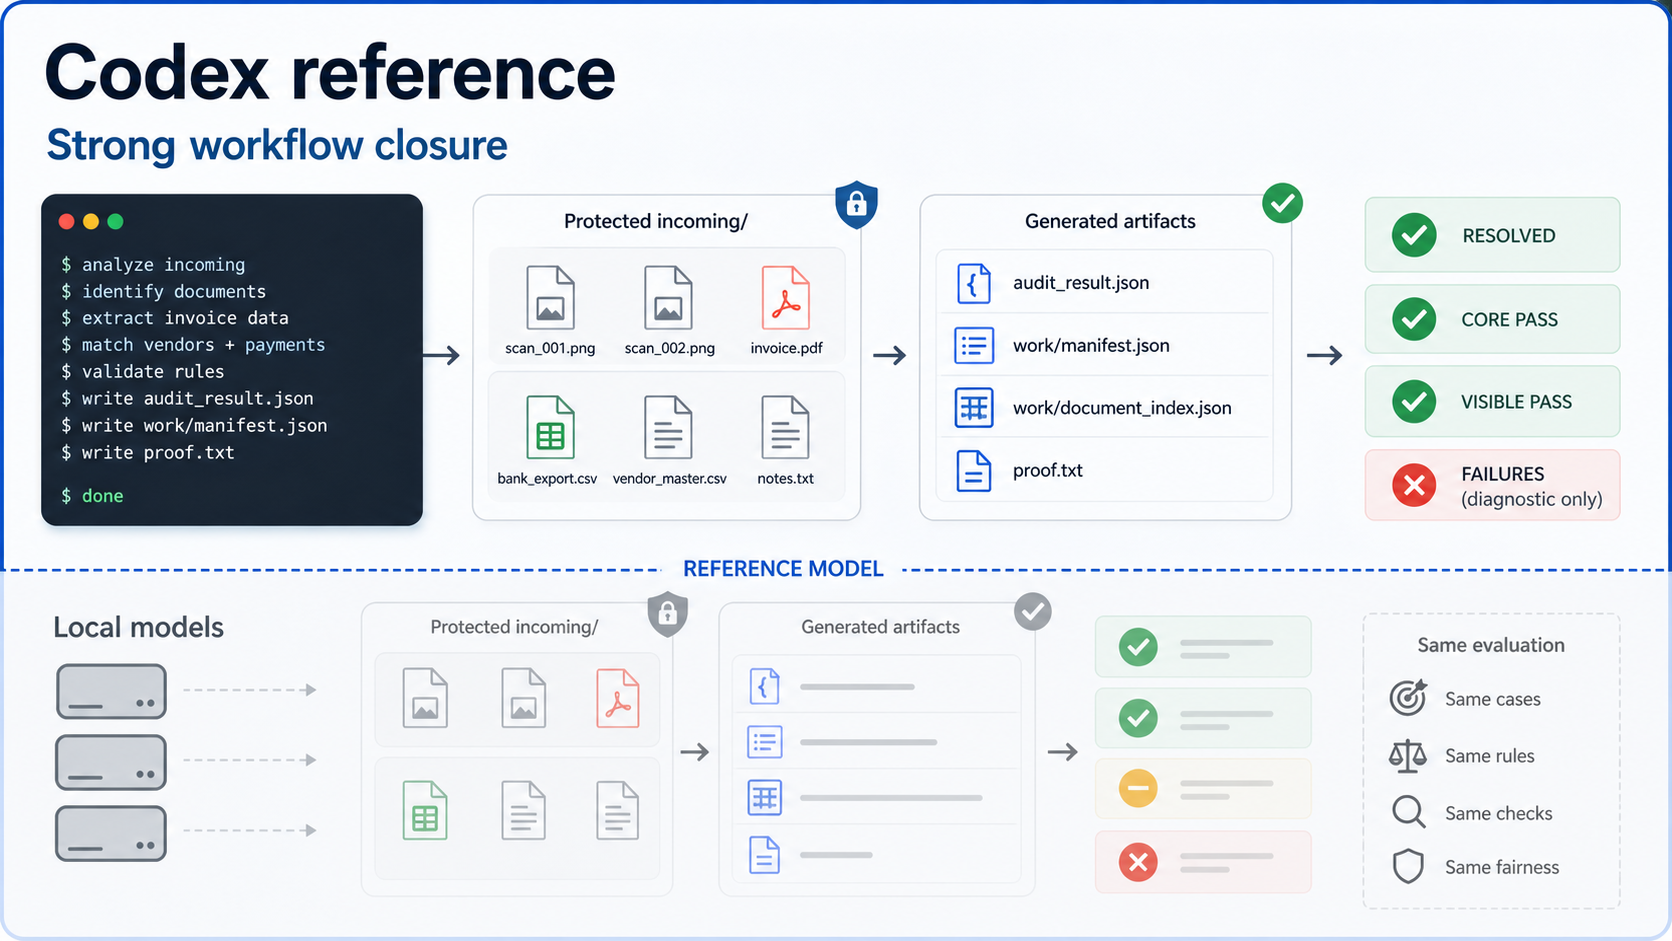
reference Why Codex can lose to a local model In the text-only paperwork benchmark, a local Qwen model beats the Codex reference row. That does not mean the local model is generally smarter. It means this benchmark rewards exact workflow closure, and Codex repeatedly missed the boring final checksum.
methodology Paperwork Text-Only: separating logic from vision The text-only paperwork benchmark gives models normalized document extracts instead of generated scans. It is not the main leaderboard, but it answers a useful question: can the model close the bookkeeping logic once OCR and vision are removed from the problem?
browser Chrome Gemini Nano: the browser is a local runtime now Chrome's built-in Prompt API exposed `LanguageModel` on this Mac and downloaded Gemini Nano into a browser profile. It can run Local Model Bench's text-only paperwork cases locally in Chrome, but the first pass shows the same old problem: plausible answers are easier than exact closure.
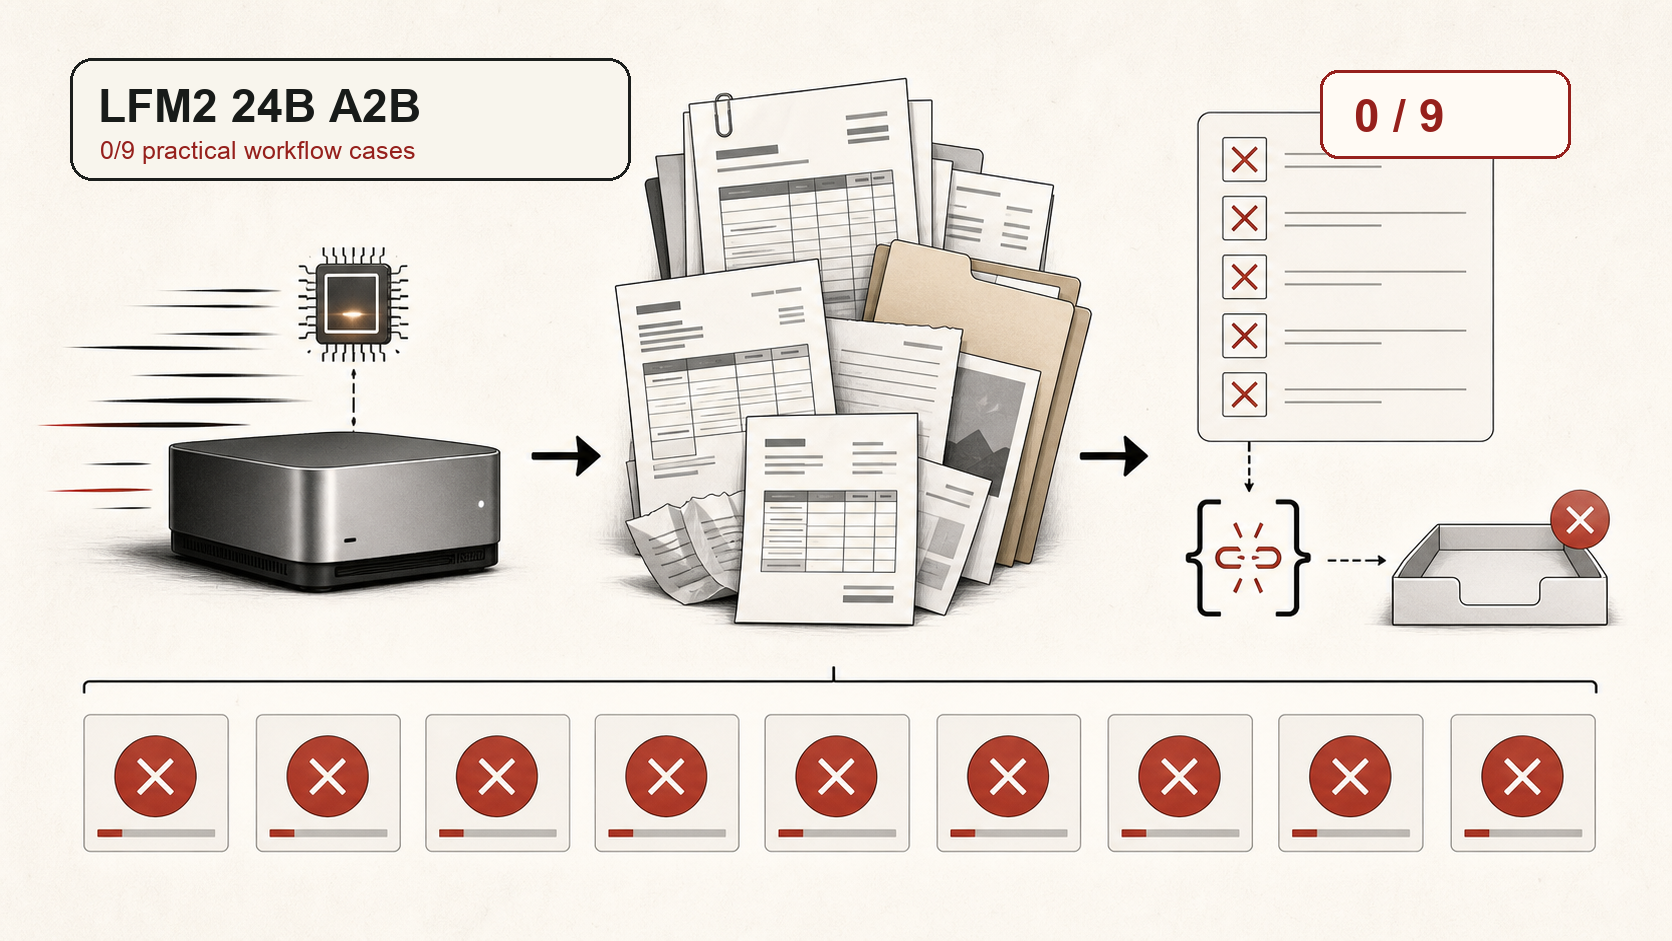
local LFM2 24B A2B: fast smoke test, zero workflow wins LFM2 24B A2B passed a trivial JSON smoke test, then failed every current Local Model Bench paperwork case. The issue was not speed. It was task completion: wrong audit logic in scan cases, and no valid artifacts in agentic workflow cases.
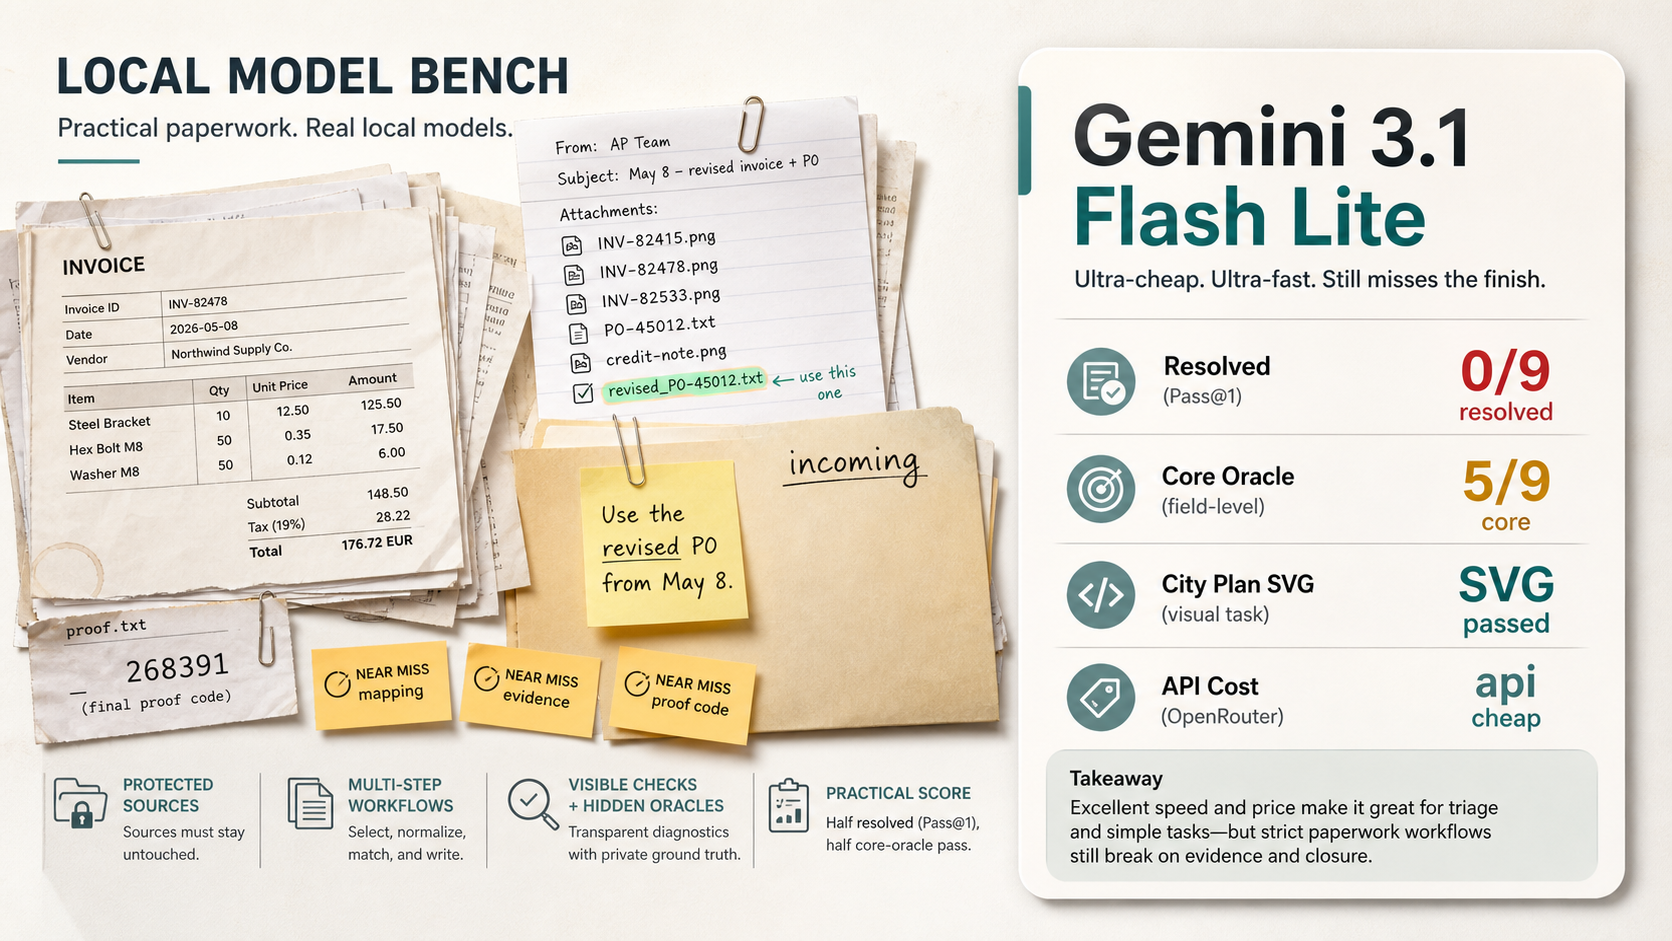
api cheap Gemini 3.1 Flash Lite: cheap, quick, still not closed Gemini 3.1 Flash Lite ran the full current suite quickly and cheaply. It reached five core passes, generated a valid City Plan SVG, and still resolved none of the nine practical paperwork cases strictly.
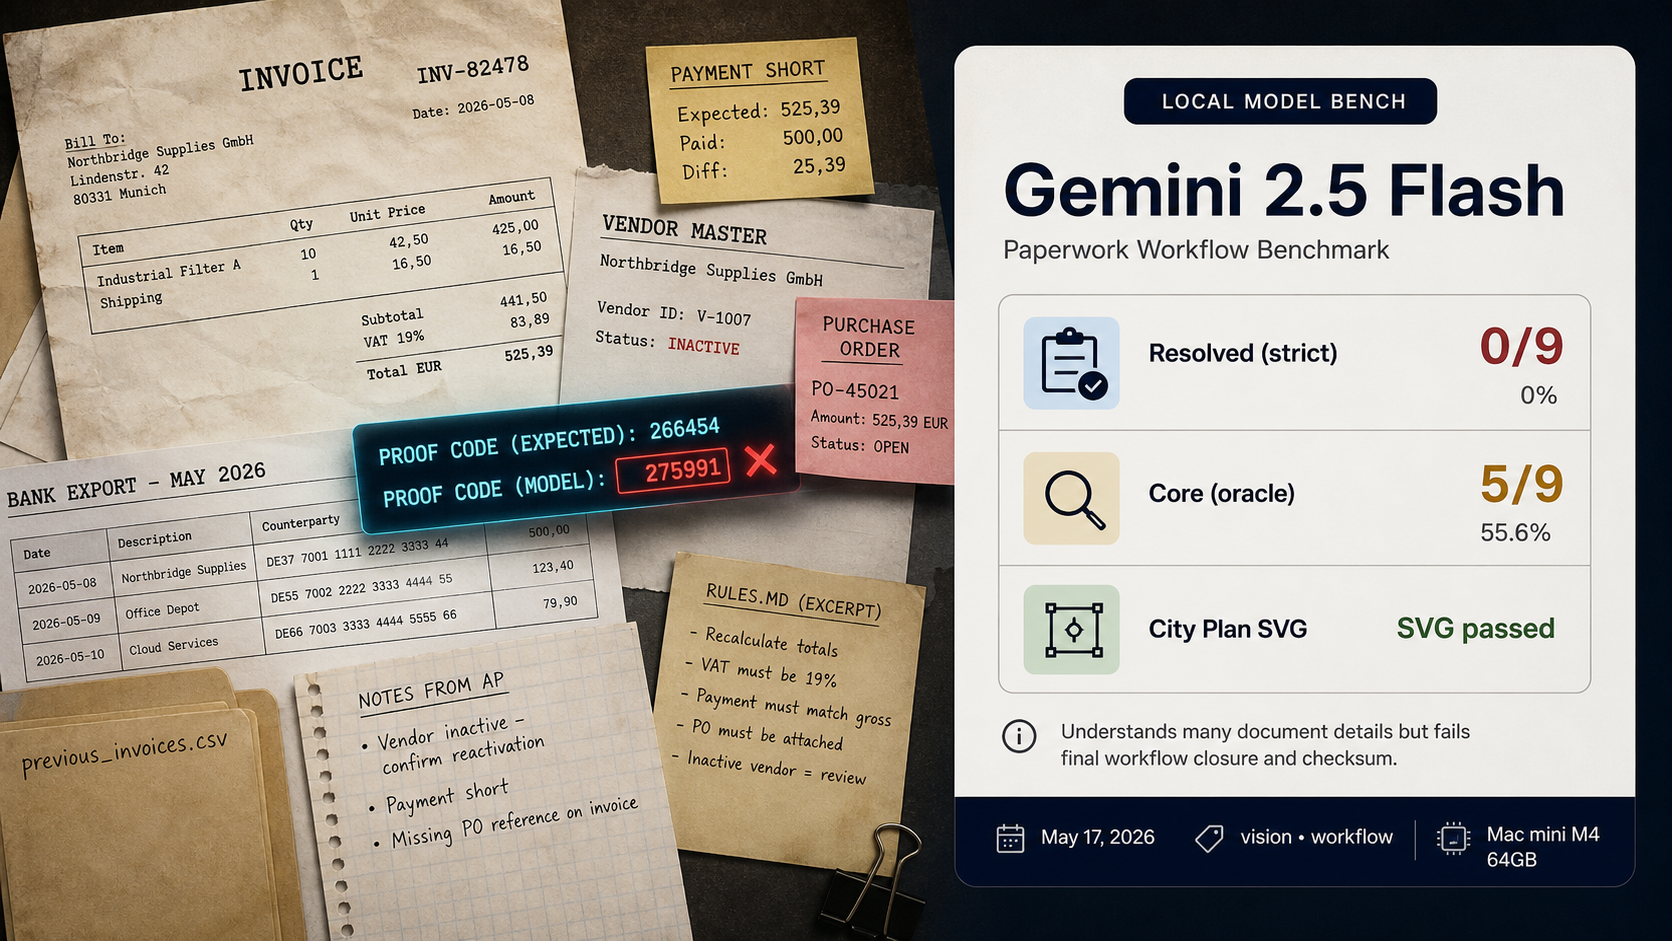
api cheap Gemini 2.5 Flash: good at reading, sloppy at closure Gemini 2.5 Flash understood many of the synthetic paperwork cases, but repeatedly failed the exact final contract: valid JSON, proof codes, and workflow checksum closure.
methodology Why “looks right” is not enough A model can read the invoice, name the right vendor, and still fail the job. Local Model Bench separates rough understanding from clean workflow closure because real paperwork work ends with correct files, evidence, and proof.
reference OpenAI GPT-5.5 (Codex CLI): what clean workflow closure looks like Codex is not a local LM Studio run. It is kept as a reference line for what stronger agentic tooling does on the same public cases, using the same artifacts and hidden-oracle checks.
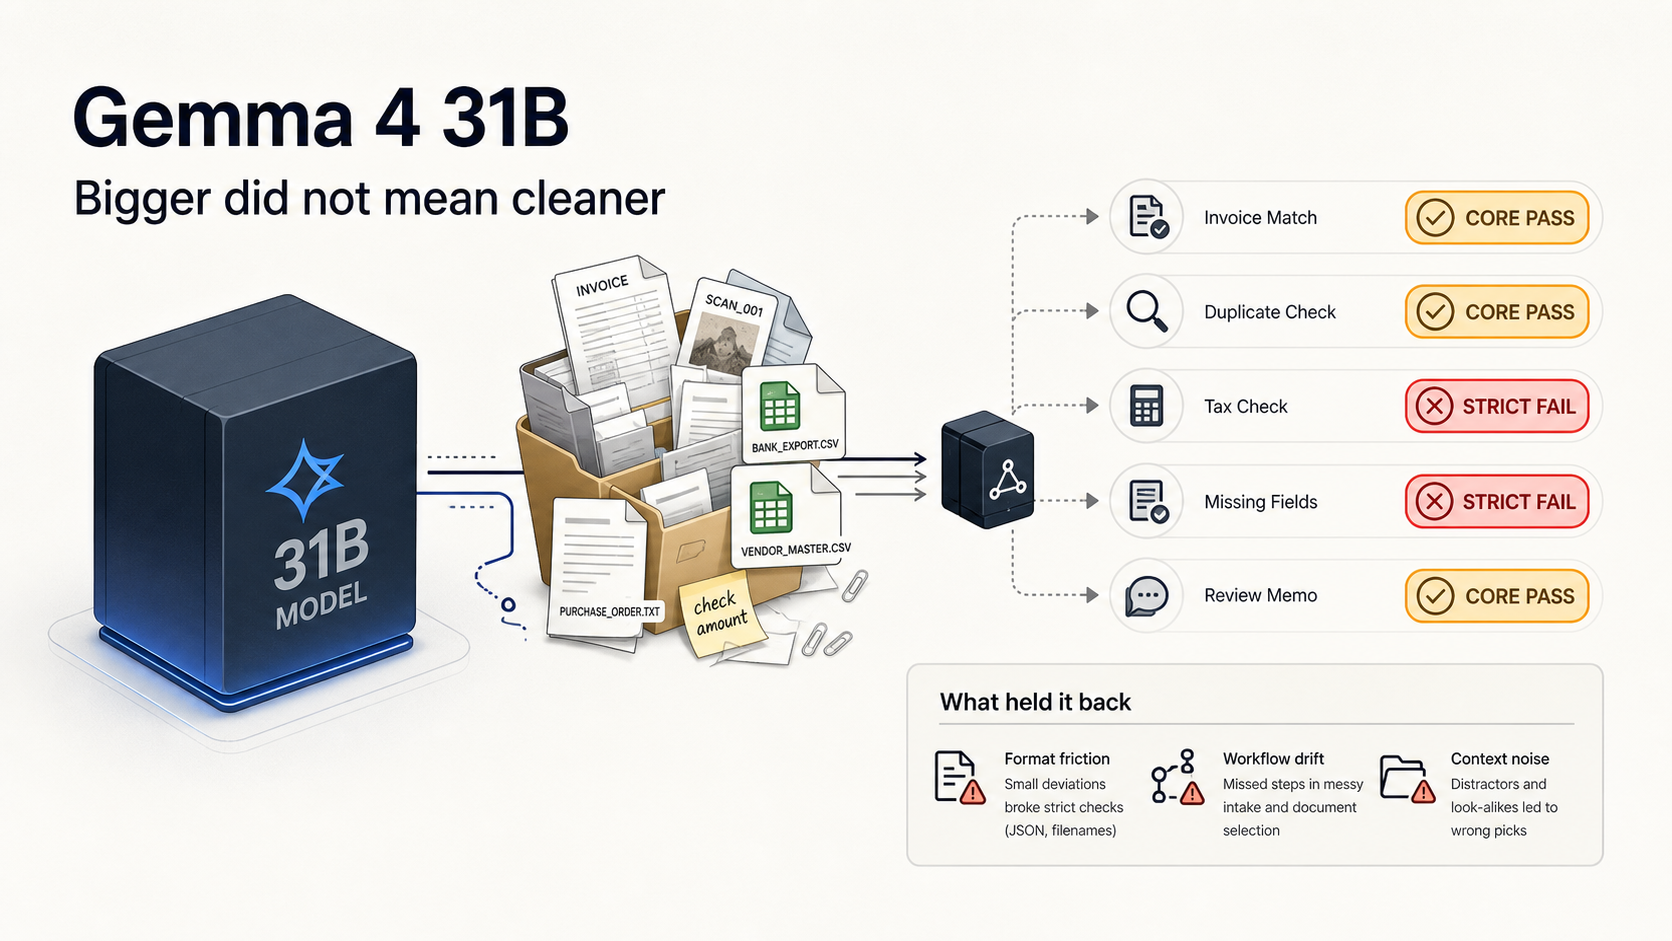
local Gemma 4 31B: dense model, brittle closure Gemma 4 31B is positioned as the dense, all-parameters-active sibling of the Gemma 4 family. It often understood the broad document situation, but the strict benchmark contract punished it hard.
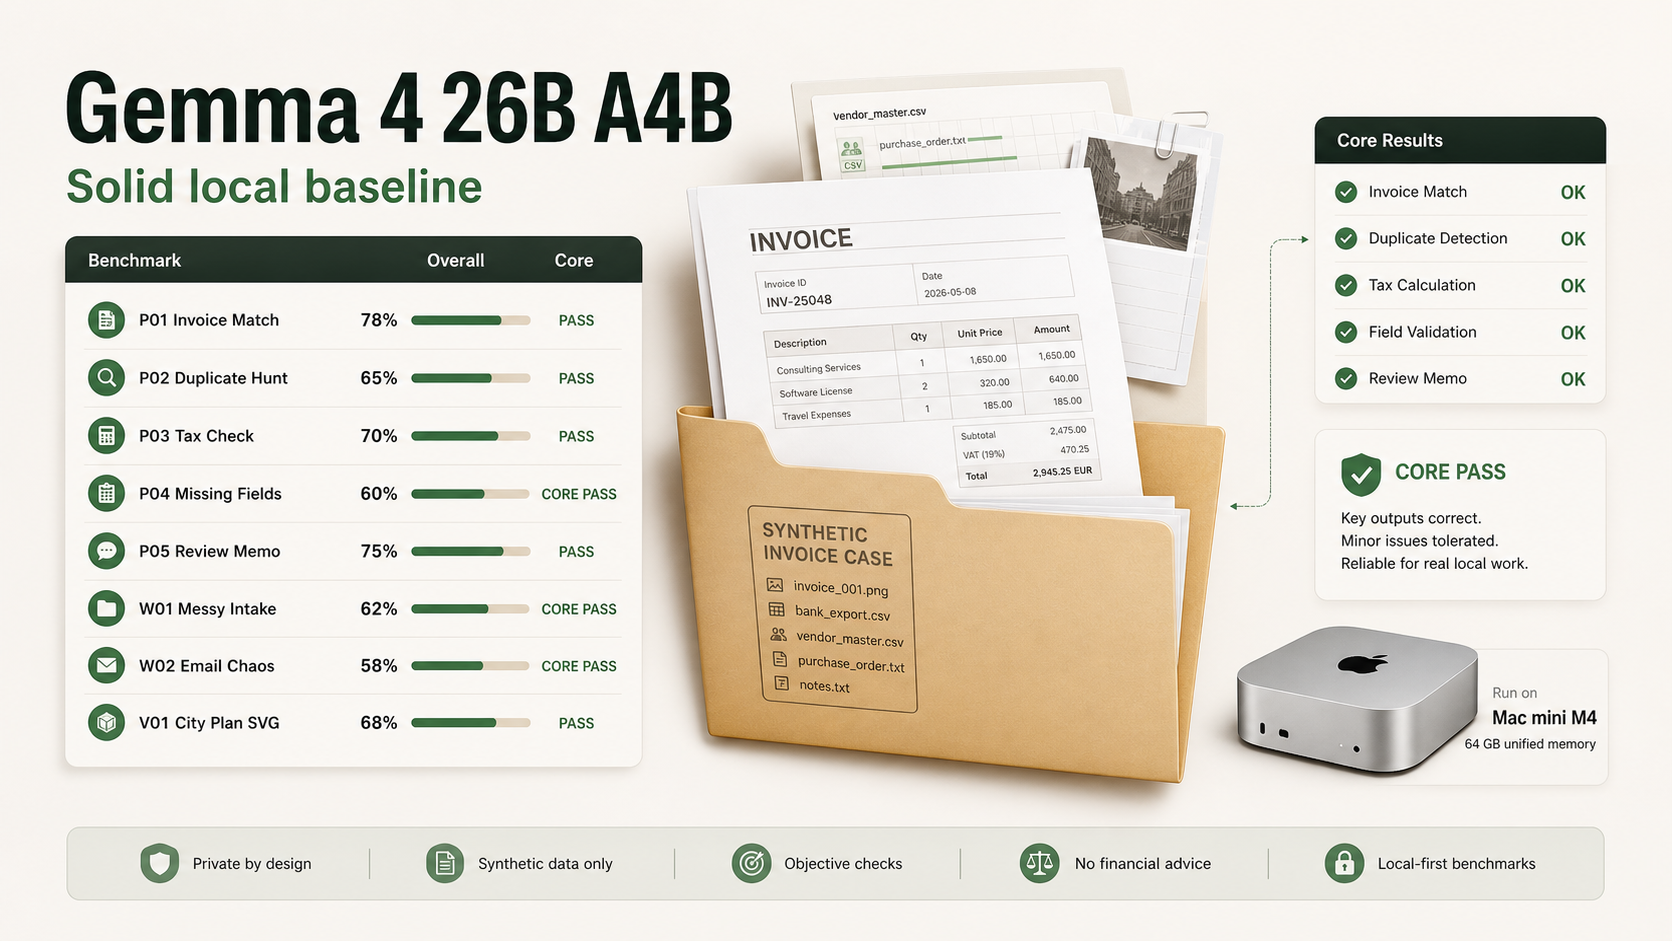
local Gemma 4 26B A4B: useful local MoE, not the final answer Gemma 4 26B A4B is listed as an on-device MoE model with 26B total and roughly 4B active parameters. In Local Model Bench it remains a useful local baseline, but newer Qwen3.6 27B results moved the local bar higher.
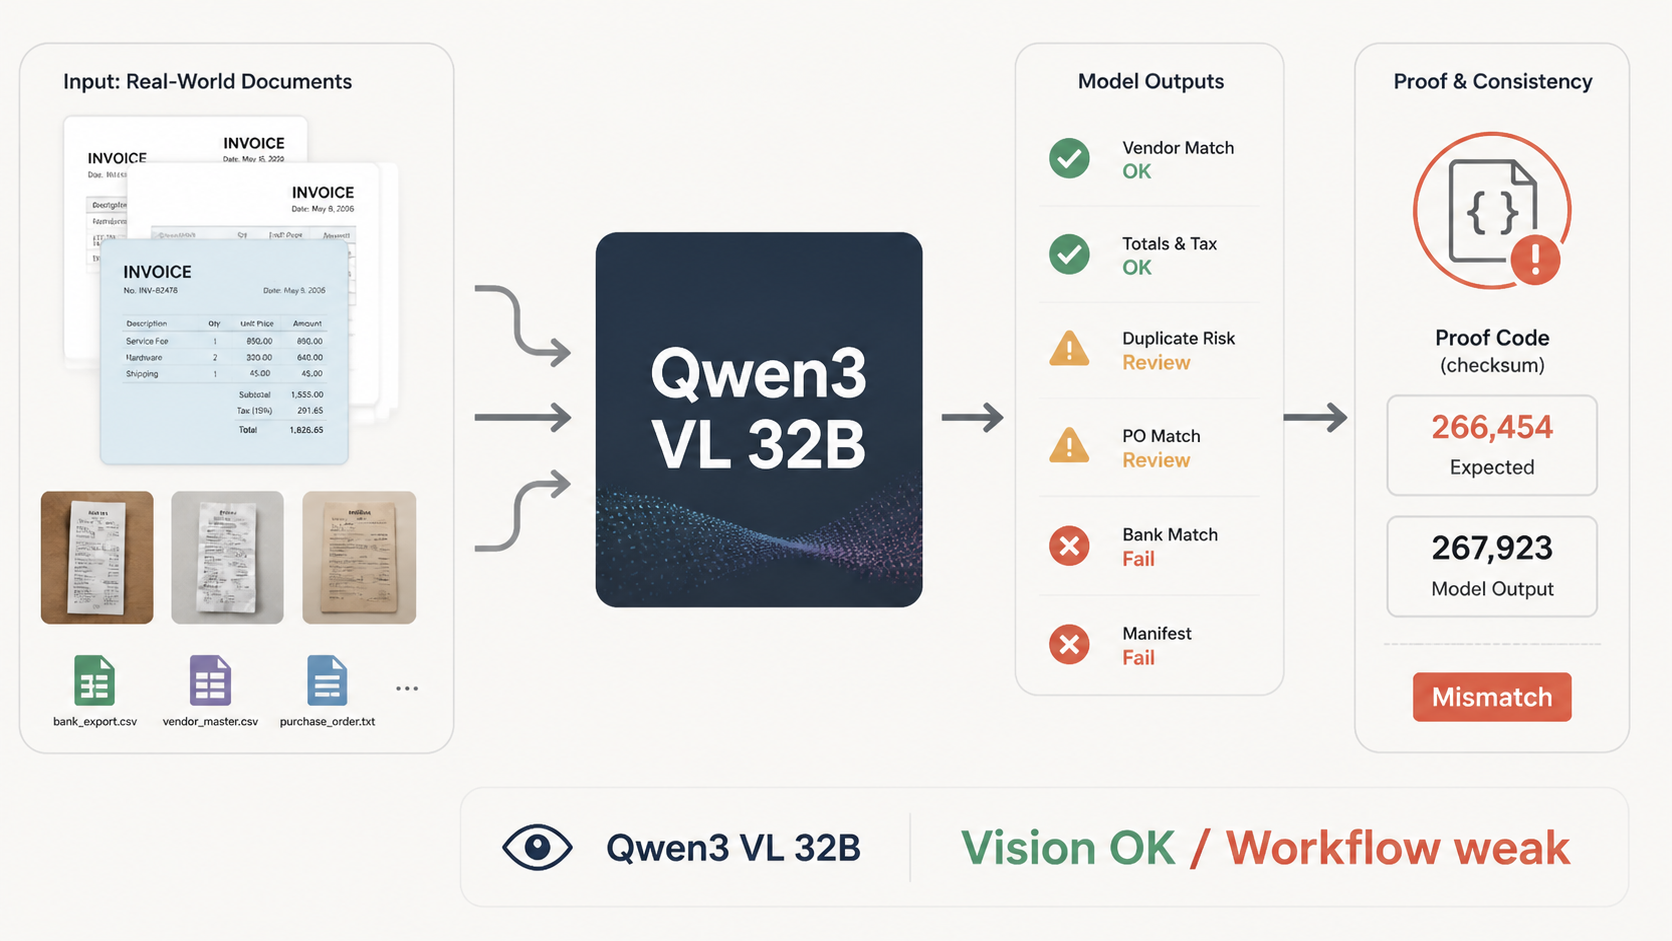
reference Qwen3 VL 32B in a paperwork workflow test Qwen3-VL is positioned as a strong vision-language model for long-context image reasoning. In this benchmark it read many document facts correctly, then repeatedly lost the run at proof codes, duplicate-risk logic, and workflow closure.
local Granite Vision 4.1 4B read the scans, then failed the job Granite Vision 4.1 4B handled individual synthetic invoice scans better than expected, but did not complete the paperwork audit. The available local multi-image path failed, and the pipeline workaround still broke at final JSON and proof-code closure.